Intelligent Document Processing for Insurance: Key Use Cases and Benefits
Updated 07 Oct 2026
17 Min
150 Views
Intelligent Document Processing (IDP) is changing how insurers handle the massive flow of paperwork that powers daily operations. By combining Artificial Intelligence (AI), machine learning, and natural language processing, IDP systems can classify and deliver structured data from unstructured insurance documents like claims forms and medical reports.
At Cleveroad, we've developed software solutions for the insurance industry for over 15 years. Starting with early machine learning models, we've grown our expertise to deliver modern IDP solutions powered by advanced AI to automate underwriting and claims workflows. We've interviewed Cleveroad's Insurance domain experts and IDP integrators to prepare this comprehensive guide.
In this guide, you'll learn:
- What IDP in Insurance is and how it differs from legacy automation tools
- Why insurance companies need IDP now, and what operational problems it helps solve
- Key 4 intelligent document processing use cases for insurance processes automation, including claims, underwriting, and compliance
- A step-by-step IDP implementation roadmap, from insurance process scoping and feasibility analysis to solution rollout
- Common challenges of IDP in insurance you may face, and our experts' tips to overcome them
What Is Intelligent Document Processing in Insurance?
Intelligent Document Processing is an AI-based technology that automates the entire document lifecycle, replacing time-consuming manual processing with faster, more accurate machine-led workflows.
Unlike traditional Optical Character Recognition (OCR), which simply converts printed or handwritten text into digital text, IDP understands document context. Intelligent Document Processing combines Machine Learning (ML), Natural Language Processing (NLP), and computer vision to:
- Classify the type of document (e.g., claim forms, medical notes)
- Extract structured and unstructured data
- Interpret entities like names, dates, International Classification of Diseases (ICD) codes, and medications
- Enrich this data with insights (e.g., identify Protected Health Information (PHI), redact sensitive fields)
- Route it for human validation only when needed
How the IDP works in insurance
Intelligent document processing for insurance automates the way insurance companies handle unstructured documents by extracting key data, classifying content, and validating inputs in real time. Instead of relying on manual review, insurers can instantly route structured information into claims or underwriting systems, so decisions arrive faster, and your team handles fewer files by hand. These capabilities are part of a broader shift toward data-driven automation, which we cover in more detail in our overview of machine learning in insurance.
Below is a step-by-step breakdown of how IDP operates within an insurance workflow, especially during underwriting and claims processing:
- Data capture. All documents, such as scanned PDFs, faxes, and emails, are routed into a centralized intake system to unify processing of structured and unstructured inputs.
- Classification. The system sorts documents automatically: claims forms go to structured extraction, while handwritten doctors’ notes enter an NLP pipeline.
- Extraction. AI models extract key document fields (e.g., policy number, diagnosis, treatment) and label entities so downstream systems can consume them.
- Enrichment. NLP models powering IDP detect entities like diagnosis codes or accident details, flag risks, and redact sensitive data by access level.
- Review and validation. If the system's confidence score for a field (e.g., 82% for poor handwriting) drops below the threshold, it flags the entry for human validation, optimizing effort where needed.
- Ready for business decisions. Clean, structured data flows directly into the claims database, enabling real-time analytics and faster decision-making.
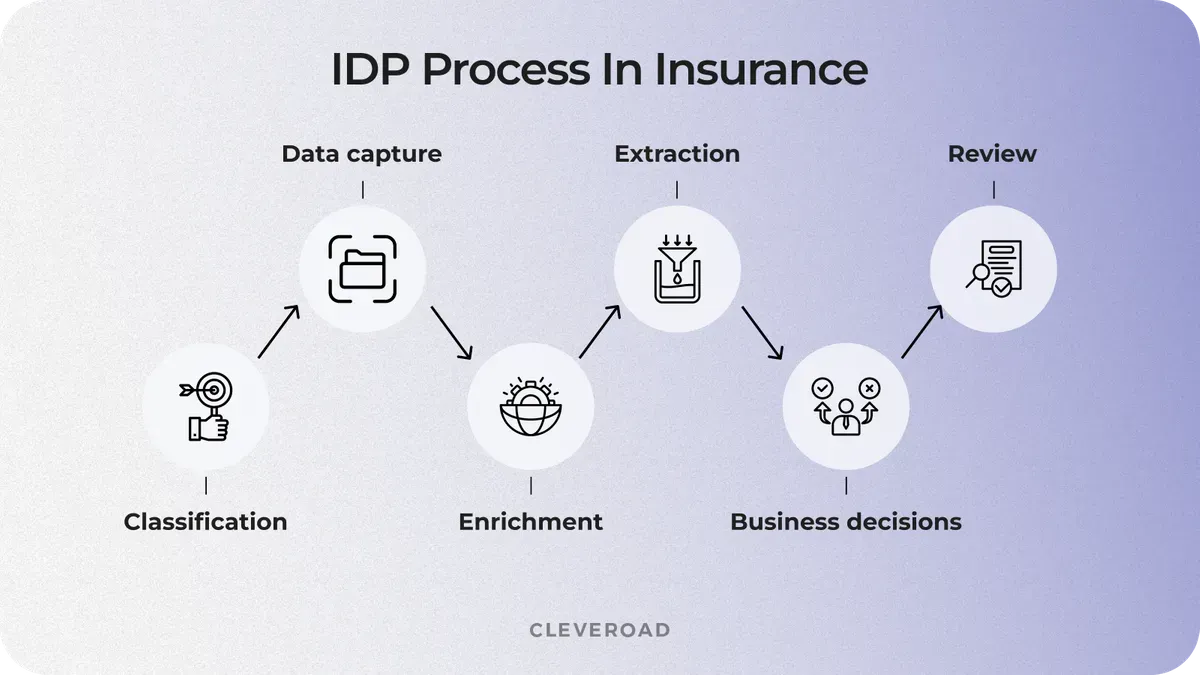
IDP process in insurance
IDP vs. OCR and RPA: What's the difference?
Unlike OCR and Robotic Process Automation (RPA), IDP platforms for insurance adapt to variations in form structure, language, and content. This adaptability suits insurance document processing, where documents differ from claim to claim and interpretation is critical. In the table below, we've prepared the core differences between intelligent document processing in insurance and other related technologies:
| Technology | What technology does | Technology limitations |
|---|---|---|
OCR | Converts the image text into machine-readable form | No context understanding; can't handle handwriting or complex layouts |
RPA | Mimics rule-based user actions (e.g., copying fields between systems) | Breaks with document variability; lacks learning capabilities |
IDP | Understands document content, learns from data, and automates workflows | Needs labeled training samples per document type; low-confidence fields still go to human review |
Why Insurance Companies Need Intelligent Document Processing
Four pressures push insurers toward IDP: document volume, the labor cost of manual entry, the speed customers expect from claims and underwriting, and regulators who now examine AI models as well as data. Below, each pressure is paired with what IDP for insurance changes and the figures that back it.
Growing document volume
Insurers process thousands of documents daily, such as claims, policy applications, doctor notes, and more. As digital channels grow, the volume and variety of unstructured content grow too.
IDP solution:
Intelligent document processing for insurance enables faster document intake and triage. AI models automatically sort, classify, and extract data, scaling operations without increasing staff. In a 2025 paper published in the International Journal of Science and Research Archive, Ramesh Pingili reports that IDP "reduces document processing time by 80% and error rates by 90%" compared to manual methods.
High manual labor cost
Data entry experts and claims adjusters spend countless hours reviewing PDFs, emails, and attachments, often duplicating work across systems. Labor-intensive processing slows operations and increases overall costs.
IDP solution:
Automated document processing replaces manual extraction, and the savings show up in the cost of each handled document. Every claim or policy file that passes extraction and validation without a human touch removes a data entry step, and your staff time shifts to exceptions and decisions. McKinsey makes the same point at industry level in its July 2026 CEO guide to AI in insurance, noting that AI can materially lower the unit cost of many underwriting and claims tasks, along with routine policy servicing.
Need for extra speed and accuracy
Underwriting and claims decisions are time-sensitive, and every day of delay costs you customer goodwill and sometimes the sale itself. Errors in document interpretation add compliance risk and wrongful payouts on top.
IDP solution:
IDP pipelines for claims processing reduce turnaround time while enhancing accuracy. NLP-powered extraction and auto-validation minimize errors and shorten every step where a person used to retype or check data.
Ant Group researchers measured this effect in A Dialogue-based Information Extraction System for Medical Insurance Assessment, a 2021 preprint by Shuang Peng, Mengdi Zhou, and colleagues. Their system extracted claim details from assessor conversations automatically. It cut the average assessment procedure from 55 to 35 minutes (–36%) and saved 30% of human resources costs.
Regulatory pressure
Insurance operations must comply with the Health Insurance Portability and Accountability Act (HIPAA), the General Data Protection Regulation (GDPR), the Digital Operational Resilience Act (DORA), and regional data retention rules. Manual document processing makes consistent redaction and auditability hard to prove.
IDP solution:
Intelligent document processing in insurance can automatically redact sensitive data such as PHI, protect documents with digital audit trails, and enforce consistent handling rules. A 2025 International Journal of Science and Research Archive paper reports that compliance review time fell from 2–4 months to about 2 weeks, an 85% reduction, due to automated controls, audit logs, and built-in redaction.
IDP also creates its own AI governance requirements. The National Association of Insurance Commissioners adopted its Model Bulletin on AI use in insurance in December 2023, and by March 2025, 24 states had adopted it (Source: Quarles). For insurers, this means IDP models should have documented ownership, validation, and controls that regulators can review.
Opt for our insurance software development services to build an IDP layer with audit logging and redaction designed in from the first sprint
Key Use Cases of IDP in Insurance Workflows
In insurance, IDP pays off where documents are both high-volume and decision-critical: claims, underwriting, policy servicing, and compliance. In each workflow, it turns forms, receipts, medical records, and correspondence into fields your core systems can act on.
We've asked Cleveroad's Business Analyst, experienced in the Insurance domain, to identify the most impactful use cases of intelligent document processing in insurance. Here's our list of IDP use cases for different insurance processes:
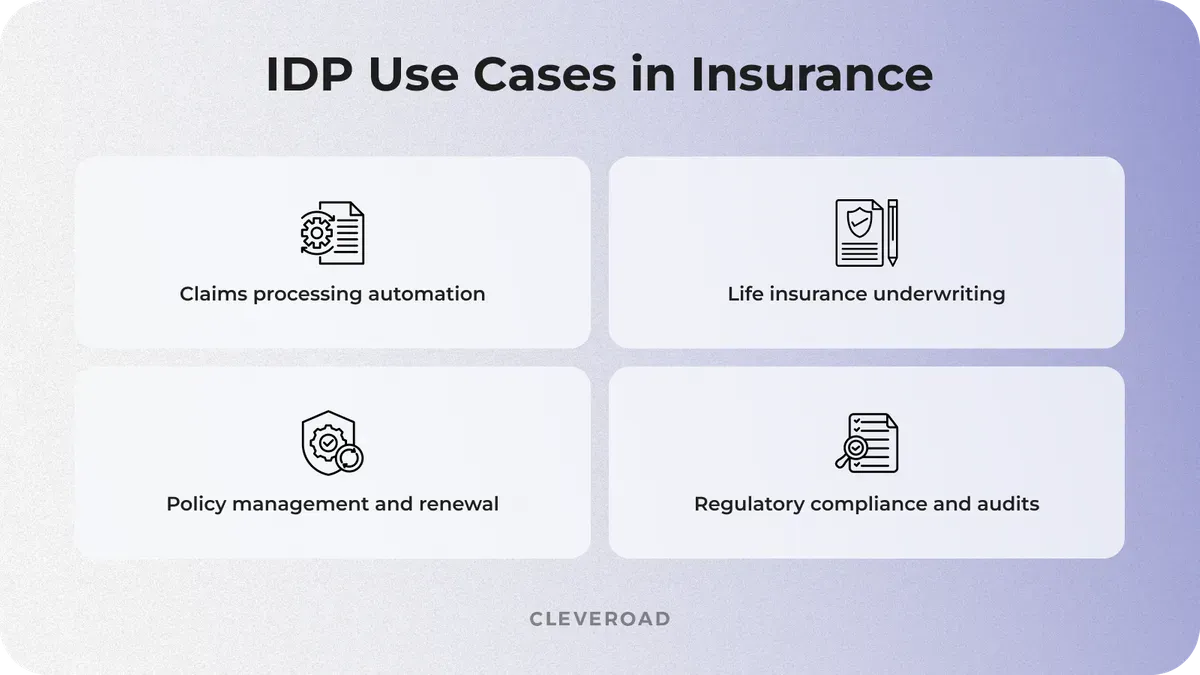
IDP use cases in Insurance
Claims processing automation
Claims processing is one of the most document-intensive functions in insurance. Speed, accuracy, and consistency are essential, and IDP supports all three by converting raw paperwork into structured information. Let's see how intelligent document processing insurance automates claims processing:
Extract info from CMS-1500/UB-04 forms, receipts, statements. IDP captures and interprets both structured and semi-structured medical billing forms, handwritten notes, and scanned receipts. It extracts key values like treatment codes or billed amounts.
Classify and process documents, mapping them to workflows. Incoming documents are automatically classified, for example, distinguishing between a provider invoice and an Explanation of Benefits (EoB). Based on the type, IDP assigns the document to the correct claims processing path.
Trigger rules for payout approval. With structured data in place, IDP rules engines can assess whether a claim meets conditions for auto-approval, requires further review, or flags for potential fraud, accelerating the claims lifecycle.
Let's examine the case of a company that implemented IDP for claims processing automation in insurance and obtained benefits:
nib Group, which provides medical insurance to more than 1.6 million people in Australia and New Zealand, uses Amazon Textract to read the claims receipts members photograph in its mobile app, replacing its earlier OCR setup. "By using Textract we've been able to speed up our claims processing, resulting in a great customer experience while at the same time increasing our operational efficiencies," says Mathew Finch, nib's Head of Emerging Technology.
Choose custom insurance claims management software tailored to your claim types, approval logic, user roles, and operational processes
Life insurance underwriting
Life underwriting requires careful evaluation of applicant risk based on documents like physician statements. IDP simplifies this evaluation and improves turnaround time. This is how intelligent document processing in insurance improves life insurance underwriting:
Analyze medical records, lab results, and ID forms. IDP systems extract critical health indicators and identity verification data from complex, multi-page files. This includes cholesterol levels, medical history, medication lists, and age verification.
Pre-screen applications faster. Underwriting engines use pre-screened data to assess initial eligibility, identify potential red flags, and assign risk levels, so your underwriters review only the files that need judgment.
Generate underwriting summaries. Once processed, IDP summarizes risk-relevant data, saving underwriters hours of manual analysis and improving consistency.
Let's take a look at the case when a company implemented IDP for life insurance underwriting in insurance and received advantages:
In an October 2024 study, Reinsurance Group of America (RGA) had eight underwriters work 109 facultative cases twice, once with traditional Attending Physician Statement (APS) review and once with AI-generated APS summaries from DigitalOwl. The AI summaries cut underwriting time by an average of 19 minutes per case, or 25%.
If you run underwriting on older infrastructure, reaching this level of automation usually means you first need to modernize a legacy insurance system before scaling intelligent document processing across underwriting workflows.
Policy management and renewal
Ongoing policy servicing requires frequent updates, often based on customer-submitted documents. IDP helps insurers reduce delays and errors in this routine but critical process. The ways in which automated document processing insurance enhances policy management:
Automate form intake. IDP captures data from structured and unstructured forms, such as address changes or beneficiary updates, and prepares it for policy systems.
Sync structured data with the Customer Relationship Management (CRM) system or policy database. Once verified, extracted data syncs directly into customer records, keeping policies accurate and reducing time spent on duplicate data entry.
Reduce processing time for updates and renewals. By removing manual steps, IDP accelerates processing timelines, improving customer satisfaction and freeing teams to handle exceptions or escalations.
Here is how one insurance company used IDP for policy management and what it achieved:
Encova Insurance, an Ohio-based mutual insurer that sells through more than 2,000 agents across 28 states, uses UiPath Document Understanding for policy intake and commercial lines endorsements. According to the UiPath case study, manual data entry for policy intake dropped from about 650 hours a month to 12.5 hours a year. Extraction now succeeds on 99% of documents, while traditional OCR processed only about 40% cleanly. For commercial lines endorsements, Encova expects a 95% reduction in annual processing time.
Regulatory compliance and audits
Insurers must prove adherence to regulations like HIPAA, GDPR, and regional insurance mandates. IDP makes audit readiness a built-in feature of daily operations. This is how intelligent document processing for insurance supports regulatory compliance:
Structured audit logs. IDP solutions log every document interaction, when it was received, processed, flagged, or modified, making compliance reviews transparent and traceable.
Fast retrieval of required documents/data. Instead of sifting through archives manually, teams can search and retrieve documents based on any extracted field, such as client name, date, document type, or keyword.
Ensure data traceability and consistency. IDP maintains data lineage, showing where each data point came from, when it was captured, and whether it's been validated, reducing compliance risk and human error.
European supervisors go a step further than the NAIC bulletin and spell out what this audit layer should contain. In August 2025, the European Insurance and Occupational Pensions Authority (EIOPA) published an Opinion on AI governance and risk management. It sets expectations for data governance, record-keeping, explainability, and human oversight of the AI systems insurers use, scaled to each system's risk. For an IDP pipeline, that translates into versioned training data and a log entry for every automated extraction, so a reviewer can trace any field back to its source document.
Try our AI strategy advisor to identify the best-fit AI use cases for your insurance operations before speaking with our team
How to Implement Intelligent Document Processing in Insurance Step by Step
At Cleveroad, we implement IDP in five stages, whether you build a custom solution from scratch or integrate it into legacy insurance systems. Each stage helps validate the approach before you commit more budget.
Now, let's see how the Cleveroad team integrates IDP into the insurance workflow.
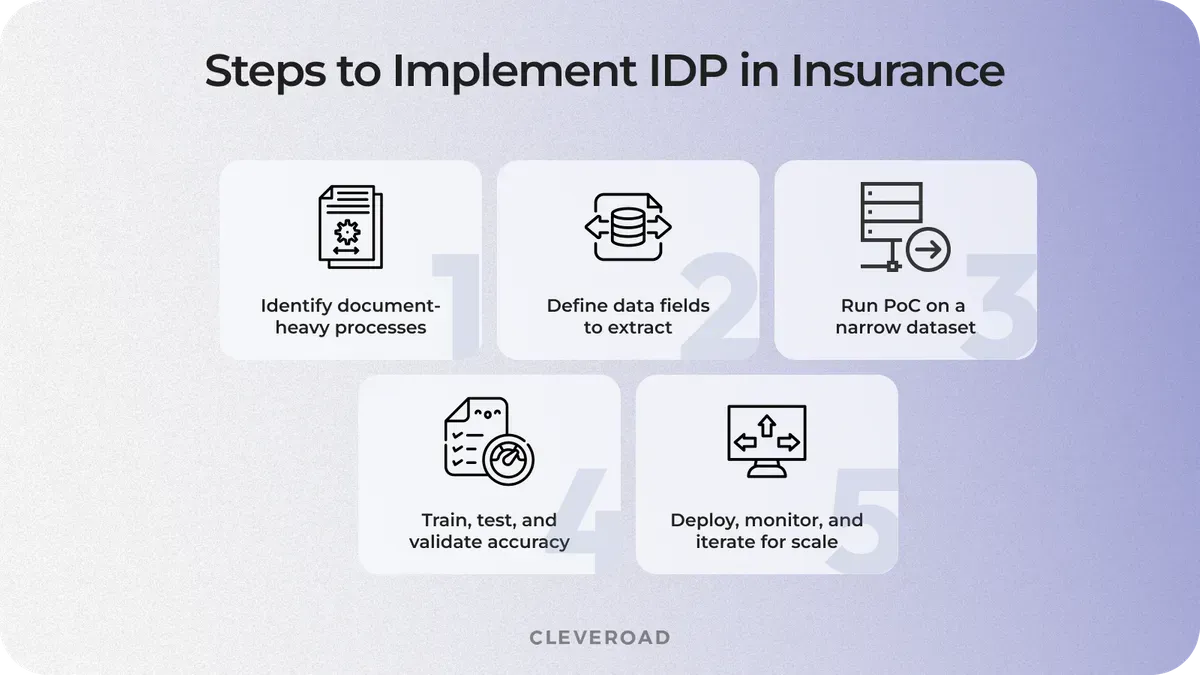
Steps to implement IDP in insurance
Step 1. Identify document-heavy processes
The first step is to assess your internal workflows. You need to decide where document processing has the greatest difficulties. Claims data handling, customer onboarding, and life insurance underwriting are typically the most document-intensive areas. Base this assessment on measurable pain points such as processing delays, error-prone data entry, compliance findings, or backlog size.
While this step starts internally, a technology partner can assist with evaluating your document flows, identifying automation-ready use cases, and benchmarking against insurance industry standards. Cleveroad experts guide the AI Workshop to help you prioritize the right processes for the highest return on automation.
Step 2. Define data fields to extract
With high-volume processes identified, the next step is to define which specific data points you need to extract and how you'll use them. In an insurance claims context, it might include policy numbers, dates of loss, and treatment codes. In underwriting, it could involve lab results or flagged risk factors.
The goal here is to align IDP outputs with your business rules, so the extracted data supports automated decision-making. Cleveroad helps map this logic, ensuring that intelligent document processing for insurance feeds structured, accurate information into your operational systems.
Step 3. Run PoC on a narrow dataset/process
Before scaling IDP across departments, it's critical to validate the concept with a focused Proof of Concept (PoC). It involves selecting a single document type or sub-process, such as accident-related claims or physician statements, and testing IDP performance on real data.
The proof of concept helps verify if your IDP idea brings a real business impact. Cleveroad rapidly develops PoC using either custom-trained AI models or fine-tuned prebuilt engines tailored to your claims documents.
Our AI proof of concept services will help you validate if IDP will bring real value to your insurance processes before investing in full-scale implementation
Step 4. Train, test, and validate model accuracy
After the proof of concept is successful, the system undergoes a training and validation phase. Here, the AI integrators expose the models to a wider range of documents and edge cases. The IDP models learn to recognize different layouts and handwriting variations common in insurance paperwork.
At Cleveroad, we validate IDP performance against accuracy thresholds, tune model weights, and apply business-specific rules to reduce false positives. This helps prepare the solution for reliable, large-scale insurance document processing.
Step 5. Deploy, monitor, and iterate for scale
The final step is deployment and continuous improvement. Once the solution meets performance and security standards, Cleveroad integrates it with your policy or claims systems using secure, API-based connections. From there, we set up performance monitoring, feedback loops from your target user of the IDP, and automated retraining protocols.
With retraining built in, your IDP engine keeps its accuracy as you add product lines or new document types arrive.
Challenges to Expect with IDP Implementation and How to Overcome Them
Most IDP delays in insurance trace back to the documents and core systems an insurer already has. In our projects the recurring blockers are inconsistent document formats, poor scans and handwriting, and legacy systems without modern APIs. Each has a known workaround.
Below are common hurdles insurers face when implementing IDP.
Variability of document formats
Insurance workflows run on documents with completely different structures: structured claim forms such as ACORD or CMS-1500, semi-structured third-party reports, and unstructured doctor's notes and correspondence. A generic extraction system tuned for one of these performs poorly on the others.
Cleveroad solves the problem of document format variability by using a modular architecture that adapts to each document type. We applied this approach in a web-based Quality Management System (QMS) for a US-based healthcare client. It runs separate modules for Documents, HR, and Training Records, each built around FDA and ISO requirements, so a change to one document domain never forces a rewrite of the others.
A relevant example is the QMS we built for Prime Path Medtech. The platform automated document and compliance workflows for medical device quality management, including FDA- and ISO-related processes.
Breanne Butler, Project Manager at Prime Path Medtech, shares her experience working with Cleveroad on the QMS platform.
Breanne Butler, Client Liaison Officer at Prime Path Medtech™
The same separation carries over to document processing. In insurance, it means one extraction schema per document family (claim forms, medical records, correspondence, third-party reports), with a classifier routing each incoming file to the right one. Adding a new form type touches one schema instead of the whole pipeline.
Low-quality scans or handwritten content
Many critical documents, especially in claims and life insurance underwriting, arrive as faxed PDFs, low-resolution images, or pages with handwritten annotations. Off-the-shelf OCR engines struggle with exactly these inputs.
We fine-tune recognition models on insurance-specific data and build the extraction layer on top of them. Scans go through preprocessing first: deskewing, denoising, and resolution normalization. Handwritten sections are routed to handwriting recognition (ICR) rather than standard OCR, which is not built for them. Any field that falls below the confidence threshold goes to a human reviewer instead of passing a guess downstream.
Integration complexity with old systems
Many insurance companies still rely on legacy core systems for claims, policy, and document management. These systems often lack modern APIs or use outdated data formats, creating friction when you try to add automated document processing.
In most cases, the core system does not need to be touched. We put an integration layer in front of it: an API facade over the existing interfaces, scheduled file exchange where no interface exists, and a message queue that absorbs the difference in processing speed between IDP and a system built for manual entry. IDP goes live without a core replacement project.
When the legacy platform is already blocking more than document processing, our legacy software modernization services cover the deeper work: core platform upgrade, cloud migration, and API integrations that bring claims, underwriting, and policy management in line with current standards.
Auditability of automated extraction
Insurance regulators ask why a system produced a particular value and who is accountable for it. A pipeline that returns an answer without showing its basis creates an exposure, not a saving.
Every extracted field carries its confidence score, the page and coordinates it came from, and the model version that produced it. Fields below the threshold go to a reviewer, and the reviewer's decision is stored alongside the original output. The result is a record that reconstructs any extraction, which is what an audit asks for.
Cleveroad's Expertise in Intelligent Automation for Insurance
Cleveroad is a skilled insurance software development company with 15+ years of domain experience. Our services cover custom insurance platforms and legacy system modernization, along with UI/UX design and third-party integrations. For document-heavy workflows, we build AI solutions on OCR and Natural Language Processing models trained on insurance data.
Our development processes meet ISO 27001 security and ISO 9001 quality standards, ensuring secure handling of sensitive insurance data like Personally Identifiable Information (PII) and PHI. We also offer integration with existing claims, underwriting, and CRM platforms through API-driven middleware, enabling automation without disrupting legacy systems.
Choosing Cleveroad to implement IDP in insurance, you'll get:
- AI Workshop stage to gain clarity on your IDP idea, considering its use cases, business value, and how it can be executed, from goals and scope to implementation steps
- Experience in integrating insurance systems with third-party solutions, including CRM, Document Management Systems (DMS), KYC and Anti-Money Laundering (AML) tools, and other platforms critical to automation and compliance
- AI PoC services to validate the compatibility and performance of an IDP solution with your insurance IT ecosystem
- Partnership with an AWS Select Tier Partner who uses AWS-native tools to accelerate AI adoption, such as Amazon SageMaker, Bedrock, AWS Glue, and more
- Experience in creating solutions in compliance with insurance standards for security, data safety, usability, and interoperability: HIPAA, Canada's PIPEDA, ACORD data standards, the ACA, and others
To demonstrate our experience in creating solutions with intelligent document processing for insurance, we'll show our recent case: AI-Driven Document Intelligent Processing.
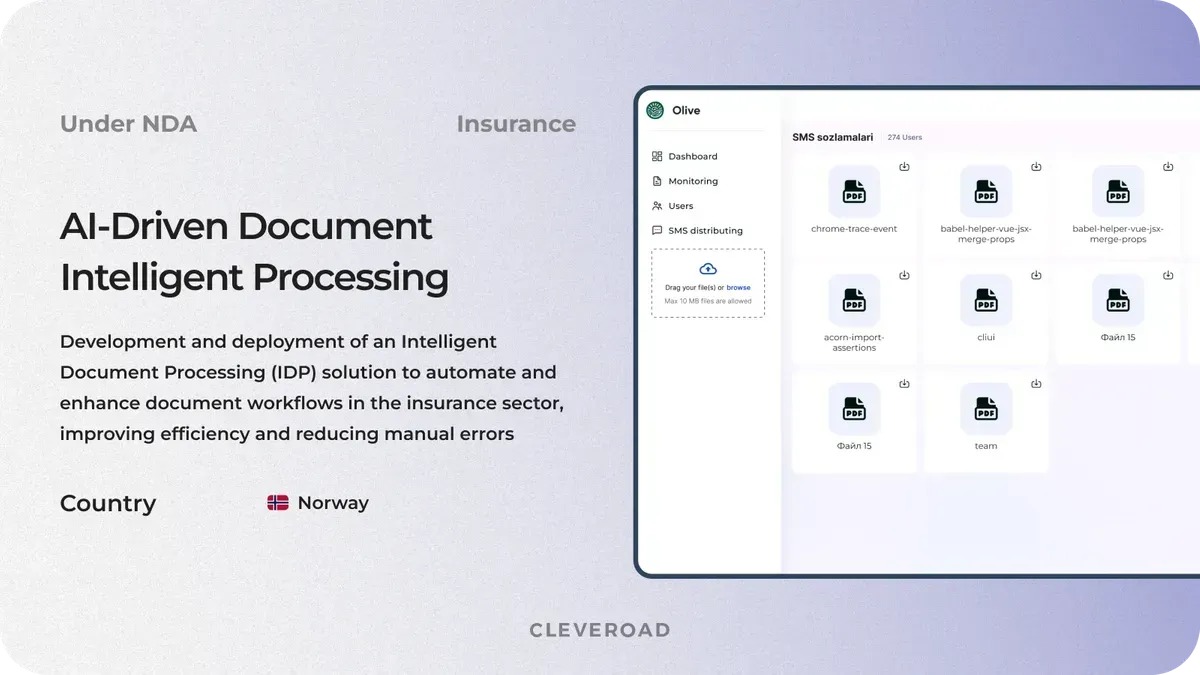
Intelligent document processing system for insurance developed by the Cleveroad team
We provided full-cycle development services for a Norway-based insurance company aiming to automate document-intensive tasks across policy and claims workflows. The client's goal was to reduce manual effort and meet compliance standards more efficiently.
Cleveroad developed a custom AI-powered IDP system specifically for insurance use. The solution integrates with the company's internal platforms and handles automatic document classification and high-precision data extraction, so most incoming documents reach policy and claims systems without manual data entry.
As a result, the client achieved up to 75% reduction in document processing time and strengthened compliance readiness across both claims and policy operations.
Ready to integrate IDP in your insurance business?
With 15+ years in insurance software, we'll scope which document flows are ready for automation and what accuracy you can expect
IDP is an AI-based approach that reads insurance documents in context and extracts the fields your claims and underwriting systems need, sending any field below a set confidence threshold (often 80–90%) to a human reviewer.
Insurers apply IDP in four workflows where document volume is highest:
- Claims processing: CMS-1500 and UB-04 forms, receipts, and EOBs
- Life insurance underwriting: lab results and Attending Physician Statements
- Policy management: intake, renewals, and endorsements, where Encova expects a 95% cut in endorsement processing time
- Regulatory compliance and audits: logging and traceability that NAIC and EIOPA guidance now expects
Most insurers get from first assessment to production in five steps:
- Identify document-heavy processes
- Define data fields to extract
- Run PoC on a narrow dataset/process
- Train, test, and validate model accuracy
- Deploy, monitor, and iterate for scale
The benefits show up in two numbers you can track from day one. The first is the straight-through processing rate: the share of documents that pass extraction and validation with no manual review. The second is the time from document receipt to a claims or underwriting decision. For reference, for the Norwegian insurer we built an IDP system for, we cut document processing time by up to 75%, and as the straight-through rate grows, you can move more reviewers to complex cases.
Evgeniy Altynpara is a CTO and member of the Forbes Councils’ community of tech professionals. He is an expert in software development and technological entrepreneurship and has 10+years of experience in digital transformation consulting in Healthcare, FinTech, Supply Chain and Logistics
Give us your impressions about this article
Give us your impressions about this article